How to monitor Proxmox virtual machines

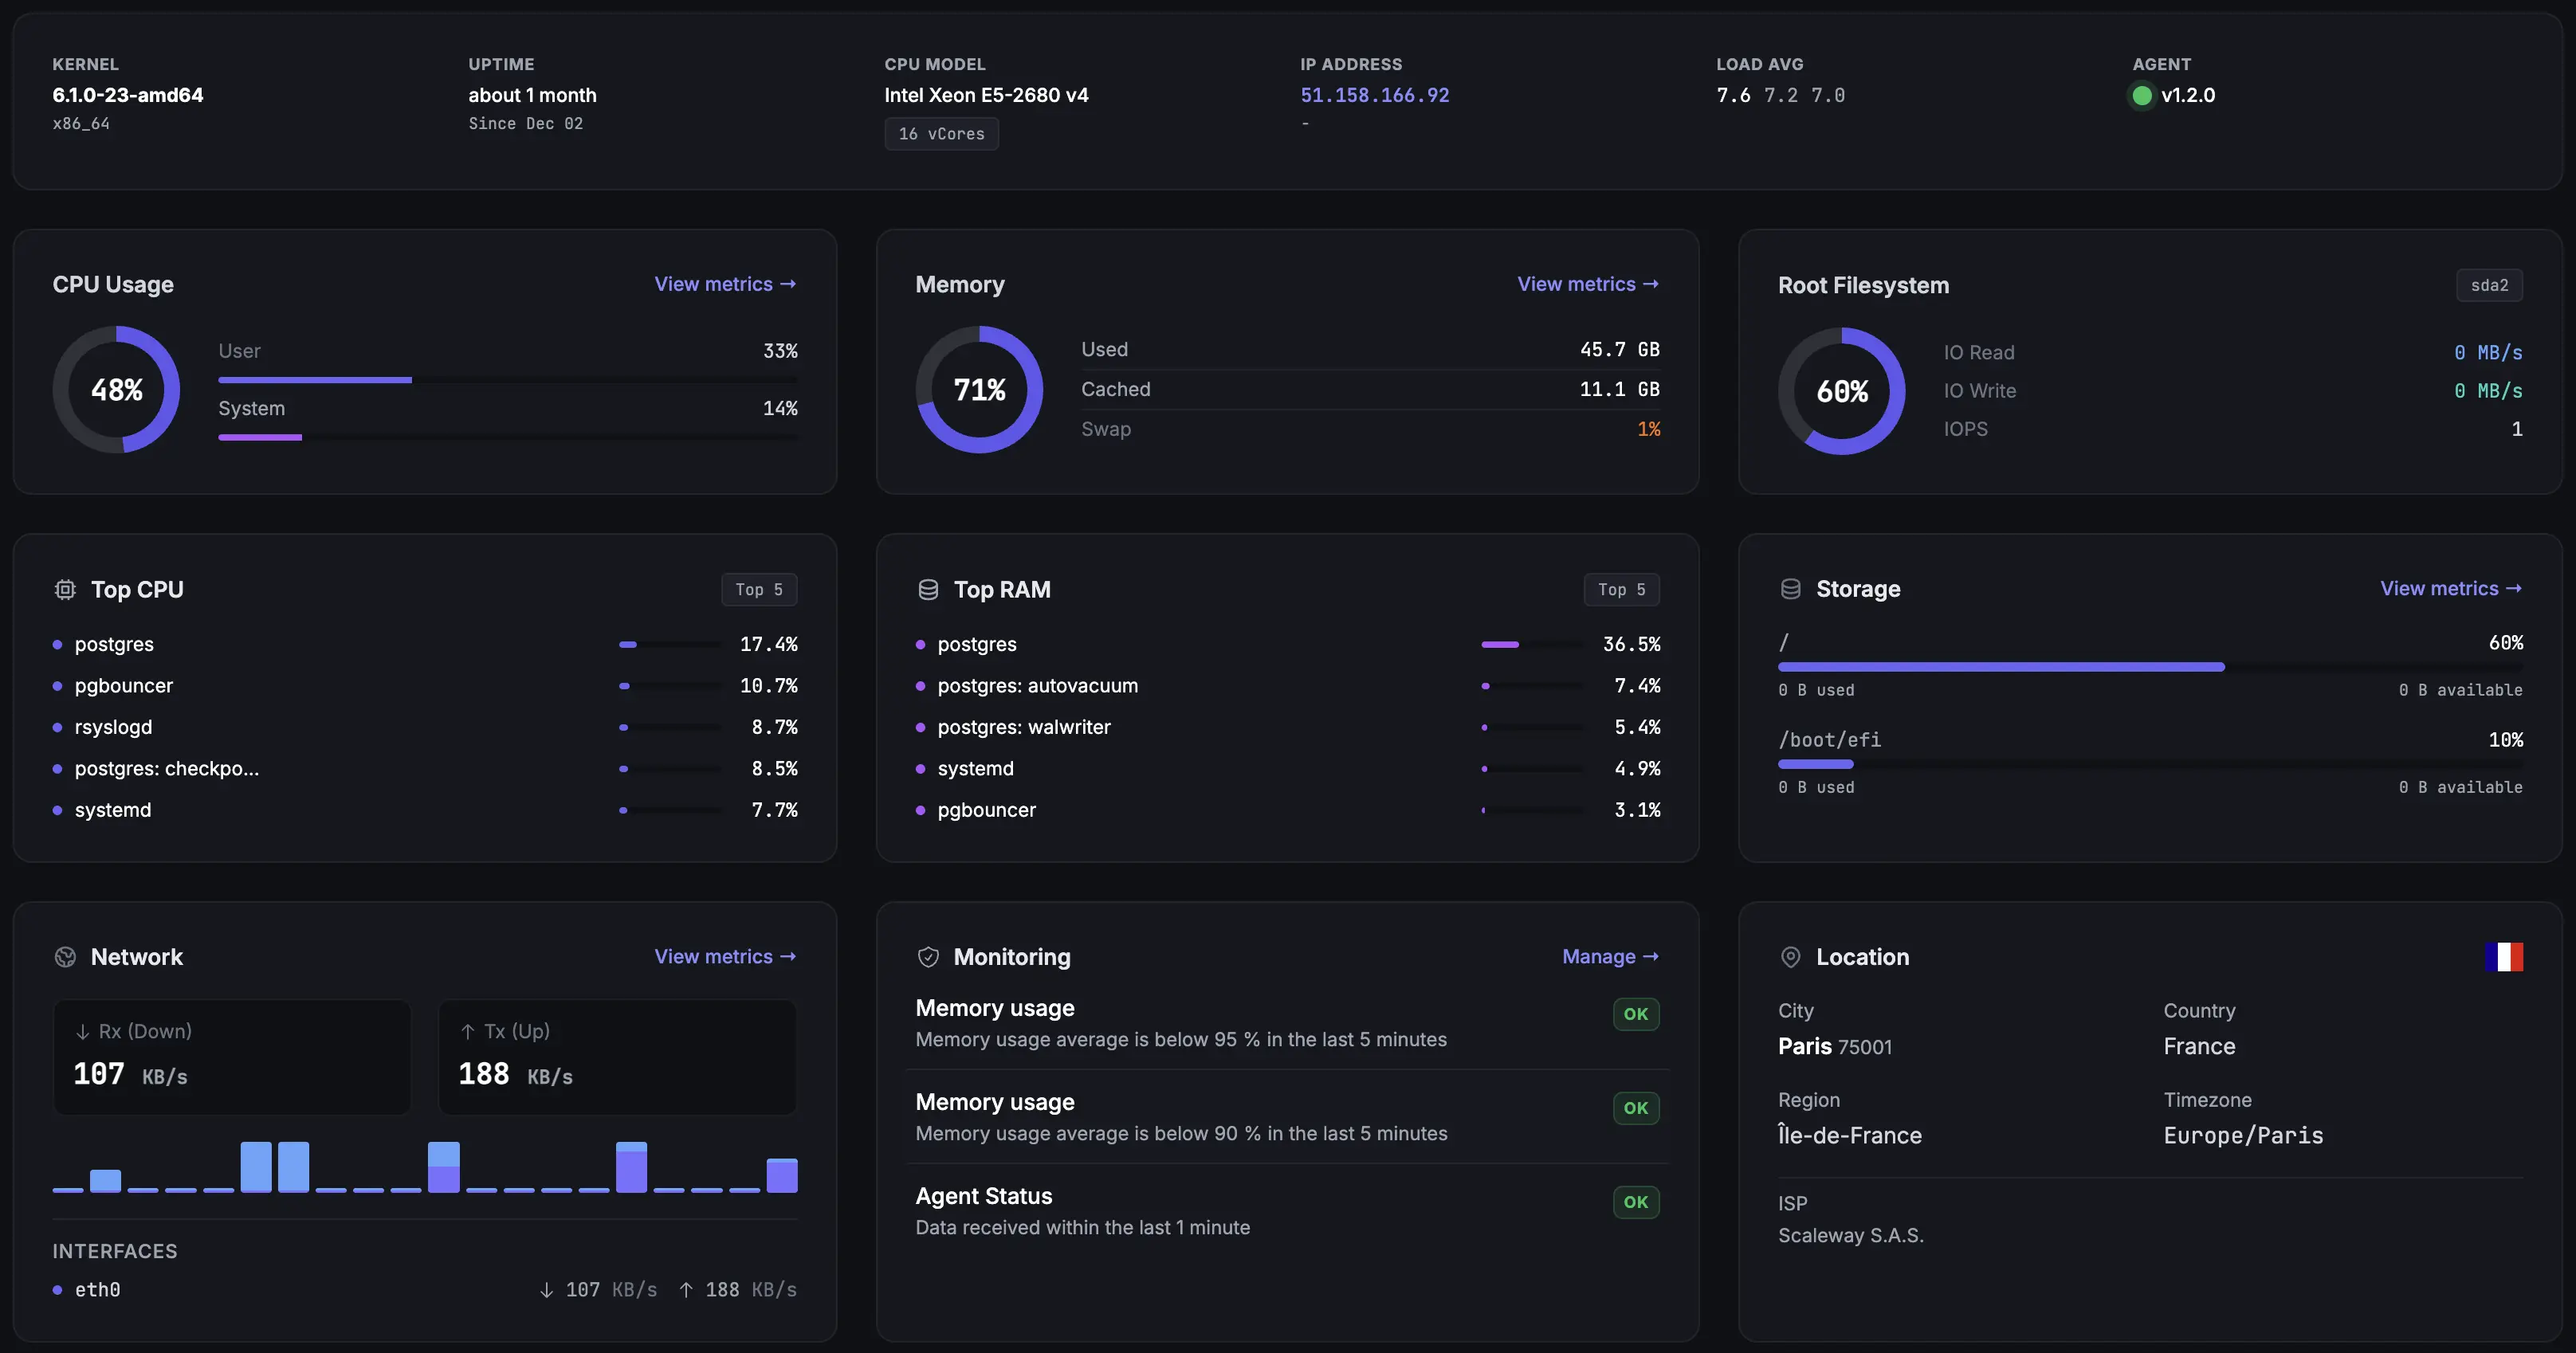
To monitor Proxmox virtual machines, start with the guest's running state, then check the node, storage and application separately. A VM can be running while its application is unavailable, and a node can have spare CPU while a storage pool is degraded. Combine Proxmox API data with host diagnostics, backup checks and an external application probe.
The local commands below run in a Proxmox node's shell as an administrator unless marked “inside the guest” or “monitoring server”. Replace the example node names, guest IDs and storage IDs with your own. Diagnostic commands inspect the system; the API-user setup creates a monitoring identity and permissions.
If you also manage standalone KVM instances outside of Proxmox, see our guide on monitoring KVM virtual machines.
How to check Proxmox VM status
For a quick check, run qm status 100 on the node hosting QEMU VM 100. For an LXC container, use pct status 101 on its node. Use the cluster resource inventory to find the current node before checking a guest that may have migrated.
# On a Proxmox node: list guests across the cluster
pvesh get /cluster/resources --type vm --output-format json-pretty

# On the node hosting the relevant guest
qm status 100
pct status 101
The inventory distinguishes qemu VMs from lxc containers and includes their node and status. Check that the guest exists in the result before interpreting its state. A missing row, permission error or failed API request is an unknown state, not evidence that a VM is stopped. The commands are documented in the qm reference, pct reference and API viewer.
For continuous monitoring, maintain an explicit list of guests expected to run, suppress alerts during planned maintenance and alert when collection stops. Pair the running-state check with HTTP, TCP or application-specific monitoring from outside the cluster: running does not prove that a database or website inside the VM is responding.
Storage Health Monitoring
Proxmox disk health: check the pool and the physical drive
A useful Proxmox disk-health check has three layers: the physical drive, the storage pool and the filesystem inside the guest. Pool capacity does not establish drive health, and a healthy drive does not establish that a VM's filesystem has free space.
# Storage configured on this Proxmox node
pvesm status

# ZFS-backed hosts only
zpool status -x
zpool status -v
zpool list -o name,size,alloc,free,cap,health

# Identify the physical device before inspecting it
lsblk -d -o NAME,MODEL,SERIAL,SIZE
smartctl -a /dev/sda
# For an NVMe controller, for example:
smartctl -a /dev/nvme0
In zpool status, inspect pool and device states, READ/WRITE/CKSUM counters, the scrub or resilver result and any permanent data errors. Investigate DEGRADED, FAULTED or UNAVAIL, as well as new errors on an otherwise online pool. Compare the last completed scrub with your own schedule; do not parse the words “No known data errors” as a numeric scrub-error count. See the OpenZFS status reference.
For physical drives, review the available S.M.A.R.T. error and self-test history, temperature and device-specific wear indicators. A passing overall health flag alone does not rule out trouble. Hardware RAID may require controller-specific options, and a virtual disk inside a VM normally cannot expose the host drive's health. smartctl is provided by smartmontools; run the physical-device check on the host with access to that device.
ZFS commands do not apply to every Proxmox storage backend. Use the relevant Ceph, LVM, NFS or storage-appliance checks for those systems, and check free space inside important guests separately. For more detail on the underlying drives, see our guide to Linux disk monitoring.
Setting Up Proxmox API Access
For ongoing collection, use a dedicated read-only identity. The example grants cluster-wide PVEAuditor access to both a user and a privilege-separated token. If you only need a subset of resources, narrow the paths and verify that your collector can still see its intended inventory.
# Run once as a Proxmox administrator
pveum user add monitoring@pve --comment "Read-only monitoring"
pveum acl modify / --users monitoring@pve --roles PVEAuditor
pveum user token add monitoring@pve monitoring-token --privsep 1
pveum acl modify / --tokens 'monitoring@pve!monitoring-token' --roles PVEAuditor
pveum user token permissions monitoring@pve monitoring-token
Save the generated secret in your monitoring system's secret store; Proxmox returns it only at creation. With privilege separation, effective access is the intersection of the user and token permissions, so assigning a role only to the token is insufficient. PVEAuditor is a built-in read-only role; Datastore.Audit is a privilege, not a role named PVEDatastoreAudit. See Proxmox user and token permissions.
Test from the monitoring server using Bash, curl and jq. The example trusts a verified copy of the Proxmox CA certificate. If the server certificate is already trusted by the system, omit --cacert instead of disabling TLS verification.
PVE_URL='https://pve1.example.com:8006'
PVE_CA='/path/to/pve-root-ca.pem'
PVE_TOKEN_ID='monitoring@pve!monitoring-token'
read -r -s -p 'API token secret: ' PVE_TOKEN_SECRET
printf '\n'

curl --fail --silent --show-error --cacert "$PVE_CA" \
  --header "Authorization: PVEAPIToken=${PVE_TOKEN_ID}=${PVE_TOKEN_SECRET}" \
  "$PVE_URL/api2/json/cluster/resources?type=vm" | jq '.data'

unset PVE_TOKEN_SECRET
Compare the returned inventory with known guests. A successful request to /version alone does not validate resource permissions. Local pvesh commands run with the local administrator's access, so they are not a substitute for testing the remote token.
Is there a Proxmox health-check endpoint?
Proxmox exposes separate API views of cluster, node and guest state. Query /cluster/status for cluster status and /nodes/NODE/qemu/VMID/status/current for a particular VM, replacing the names and ID. Containers use the lxc path. These are authenticated API paths under /api2/json, not a single end-to-end application health check. Interpret permission and collection failures separately from resource failures.
VM Performance metrics
Once status collection works, keep a history of CPU, memory, disk and network activity. Correlate the same time window across the affected guest and its host instead of inferring contention from one snapshot.
# On a Proxmox node; replace pve1 and 100 with the guest's current node and ID
pvesh get /nodes/pve1/qemu/100/status/current --output-format json-pretty
pvesh get /nodes/pve1/qemu/100/rrddata --timeframe hour --output-format json-pretty
Use /rrddata for historical data; /rrd is the graph-image endpoint. Current-status disk and network byte counters are cumulative since guest start where supported, so derive rates from changes over time and handle resets. Missing metrics are not zero usage.
For Linux guests, compare hypervisor data with measurements inside the guest. The following commands require sysstat for mpstat and iostat:
# Inside the Linux guest
mpstat 1 5
free -h
vmstat 1 5
iostat -xz 1 5
Inspect %steal in mpstat for CPU time the VM wanted but the hypervisor did not provide. Persistent increases during a slowdown justify checking host CPU load and competing guests; there is no universal percentage that proves the cause. vmstat and iostat initially show statistics since boot, followed by interval samples. The sysstat documentation explains the fields.
Memory ballooning is a configured allocation mechanism, not proof of memory pressure by itself. Compare the VM's configured memory limits, Proxmox-reported usage and guest available memory, swapping and application behavior. Neither grep balloon /proc/meminfo nor grep steal /proc/stat is a reliable check for those conditions.
For PCI-passthrough NVIDIA workloads, perform GPU monitoring inside the VM that owns the device. Do not assume a host-level collector can inspect a GPU bound to a guest.
Backup Job Monitoring
Check three different things: whether the guest is included in a backup job, whether that job completed successfully, and whether a recent backup artifact is available. A successful task alone does not prove that every required guest has a usable backup.
# On a Proxmox node; pve1 and backup-store are examples
pvesh get /nodes/pve1/tasks --typefilter vzdump --limit 50 --output-format json-pretty
pvesm list backup-store --content backup --vmid 100
pvesh get /nodes/pve1/storage/backup-store/content \
  --content backup --vmid 100 --output-format json-pretty
The task list is a limited page from one node. Check the relevant nodes, time range and pagination, then inspect the job log and result. Do not search for a VM ID inside a task's UPID string to decide which guests were backed up: multi-guest jobs and node changes make that unreliable.
For freshness, inventory the backups on the storage locations and PBS namespaces you actually use. Compare each required guest's newest available backup timestamp with its agreed recovery point objective. Handle unreadable storage, missing timestamps and permission failures as unknown; report “no backup found” only within an inventory you successfully inspected. The storage manager reference documents backup listing.
For Proxmox Backup Server, also review verification results and perform restore tests. Backup age is not proof of restorability. If you run your own backup-verification scripts, cron job monitoring for backup verification can report whether those scripts ran and signaled success; it does not establish the backup's contents on its own.
High Availability and Cluster Health Monitoring
On clustered installations, monitor quorum, expected node membership and HA-managed resources. Standalone nodes need node and guest checks, but do not have the same Corosync quorum requirements.
# On a cluster node
pvecm status
ha-manager status
pvesh get /cluster/status --output-format json-pretty
pvesh get /cluster/ha/status/current --output-format json-pretty
Loss of quorum restricts cluster configuration changes and affects HA behavior; it does not mean every running VM or storage device instantly becomes unavailable. Investigate Corosync connectivity and the HA manager's state before making recovery changes. See the cluster manager reference and HA manager documentation.
HA status describes current managed-resource state, not a migration history. Review node task logs for past migrations. For scheduled replication, inspect /nodes/NODE/replication, compare successful sync times with your recovery objective and investigate recorded errors. Replication is not a replacement for independent backups.
Security and Access Monitoring
Review unexpected administrative operations alongside resource anomalies. On the relevant node, the system journal and proxy access log provide starting points:
journalctl -u pvedaemon -u pveproxy --since '1 hour ago' --no-pager
tail -n 100 /var/log/pveproxy/access.log
Investigate repeated authentication failures, unexpected source addresses and guest creation or deletion tasks. Log availability depends on retention and configuration. A CPU spike may be a legitimate workload or a compromise; use it to direct investigation, not as a security verdict on its own.
Production Monitoring Stack
Choose a monitoring stack that covers the signals you need and that someone can maintain. Our comparison of the best Proxmox monitoring tools separates native Proxmox coverage, general server metrics and the setup each approach requires.
For a Prometheus setup, follow the Prometheus PVE Exporter installation instructions on a dedicated monitoring server. Configure its read-only token and keep TLS verification enabled. An example pve.yml is:
default:
  user: monitoring@pve
  token_name: monitoring-token
  token_value: REPLACE_WITH_TOKEN_SECRET
  verify_ssl: true
Restrict access to that file. Ensure the exporter trusts the Proxmox certificate, then start it with an explicit configuration path and a loopback listener when Prometheus runs on the same machine:
pve_exporter --config.file=/etc/prometheus/pve.yml --web.listen-address=127.0.0.1:9221For one Proxmox target, this Prometheus job sends the target to the exporter rather than scraping the exporter's root page:
scrape_configs:
  - job_name: proxmox
    scrape_interval: 30s
    metrics_path: /pve
    params:
      target: [pve1.example.com]
      module: [default]
      cluster: ['1']
      node: ['1']
    static_configs:
      - targets: ['127.0.0.1:9221']
        labels:
          proxmox_target: pve1.example.com
This is a single-target example. For a larger cluster, use the exporter's documented split between cluster and node collectors. Keep its listener on a private monitoring network when Prometheus is remote.
In Prometheus, up describes scrape success. A failed scrape can mean a collector, API, credential or network problem; it does not alone prove that a Proxmox node is down. Alert separately on collection failure and resource state, and confirm the actual exported metric names before writing rules. See Prometheus jobs and instances.
Build panels for guest state, resource trends, cluster state and backup coverage. Add host-level collectors for physical drive and ZFS diagnostics when your chosen API exporter does not expose them. Test alert delivery and recovery using a planned maintenance window, including what happens when data collection stops.
Proxmox Performance Issues
When a guest is slow, first establish whether the symptom affects one VM, several guests on a node or guests sharing a storage backend. Compare guest steal time, memory pressure and I/O latency with host load during the same interval. High I/O throughput alone does not prove a disk bottleneck.
On a ZFS host, zpool iostat -v 1 5 shows pool and device activity, while zpool status -v checks health. Treat ARC hit ratio as a workload-dependent signal: a low ratio alone does not establish memory pressure. Correlate it with host available memory, swap activity and storage latency before changing memory allocation.
For networking, inspect the relevant guest interface, bridge and physical uplink using ip -s link. Drops or errors help localize a problem, but a throughput test also depends on the sender, receiver, CPU and test settings. Separate a network symptom from an application timeout before changing the virtual network.
Reliable Proxmox monitoring combines current state, historical trends and checks outside the virtualization layer. Begin with the guests expected to run and the backups they need, then add the host, storage and cluster signals that explain failures.
The Hosting.com.tr case study shows why host and guest metrics belong in the same investigation: unusual CPU and disk activity helped the team identify compromised customer VPS. For managed coverage of nodes, guests, storage and quorum, explore FiveNines’ Proxmox monitoring.
 FiveNines